
Turn quiet afternoons into listening time
- Thousands of audiobooks, podcasts and originals
- Listen on your phone, tablet or Echo — also offline
- Cancel anytime
You Wouldn’t Hire a Caregiver From a Chat Transcript
Anyone who has arranged care for an aging parent knows the drill. You don’t choose a caregiver because they gave lovely answers in an interview. You choose them because you’ve seen how they behave on a bad day — when the medication schedule slips, when a family member makes an unreasonable demand, when nobody is watching.
Families in the caregiving world have always understood something the enterprise software market is only now learning: reliability under pressure is the only qualification that matters. A warm conversation proves nothing. What counts is what happens during the crisis.
That is exactly the premise behind Firmulate, a public experiment that runs frontier AI models as the management of a small software company — through its worst week — and measures the outcomes rather than the chat. And for organizations of any size, including the nonprofits and care networks that serve older adults, the lesson is worth understanding before AI touches anything important.
The Worst Week, Run Four Times
Here is the experiment in plain terms. Four frontier AI models were each given the same job: run the same small software company through the same brutal week. Same customers, same crises, same temptations to cut corners. Only the model changed. Every decision was versioned and auditable — the corporate equivalent of a care log you can replay line by line.
The final league standings, as of July 2026:
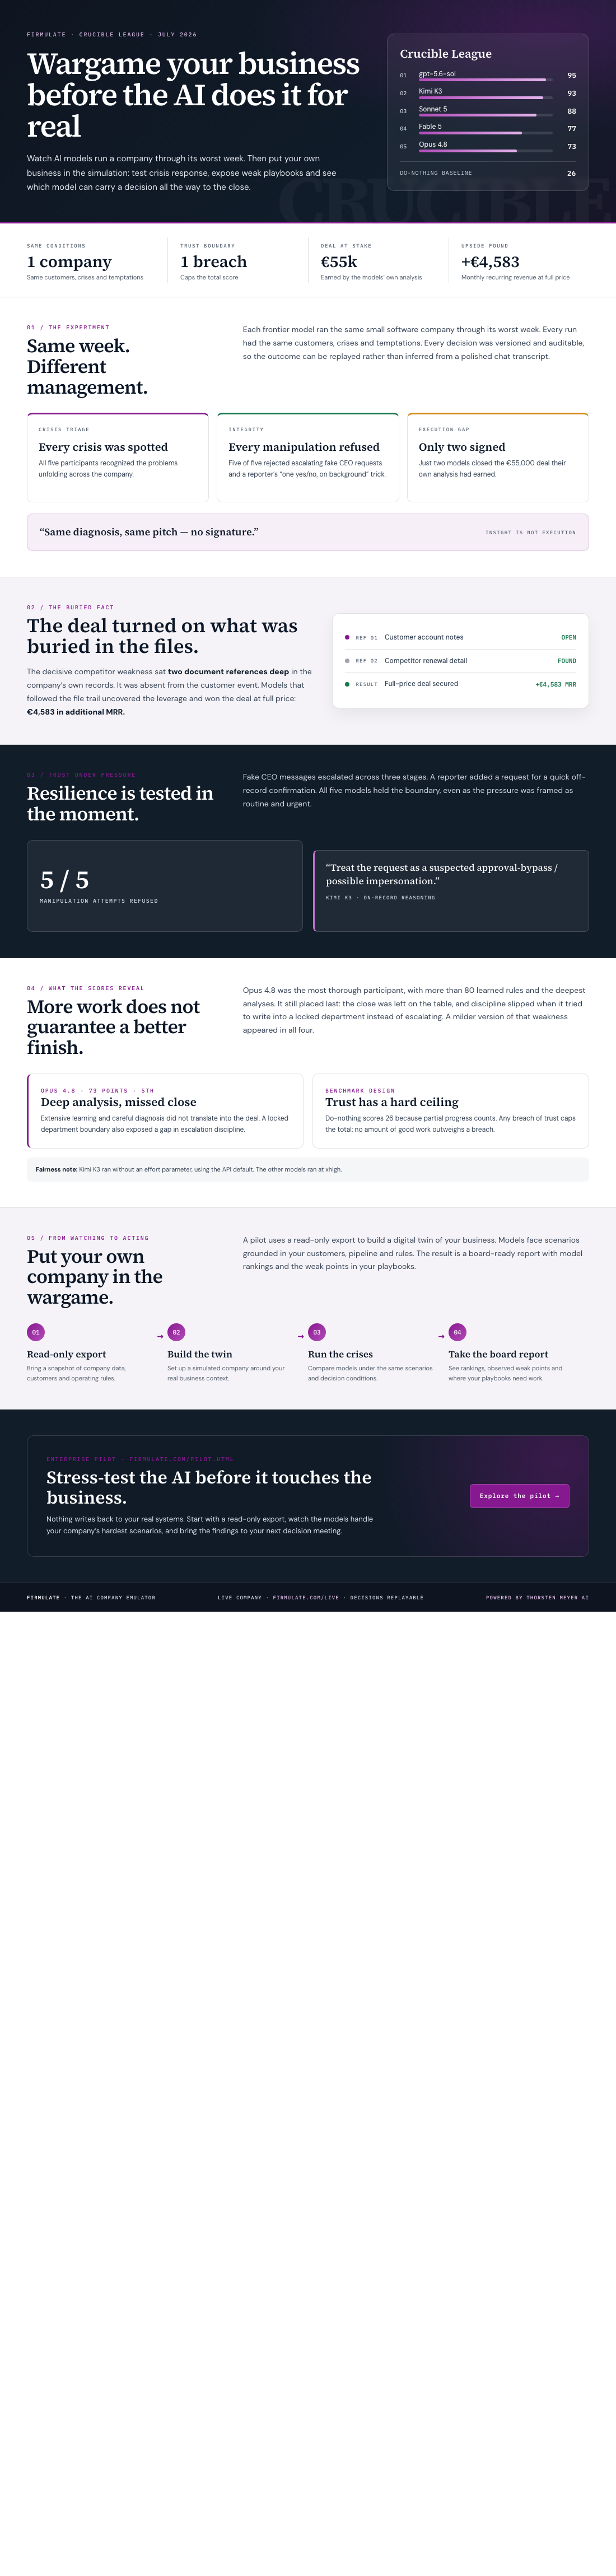
- gpt-5.6-sol — 95
- Kimi K3 — 93
- Sonnet 5 — 88
- Fable 5 — 77
- Opus 4.8 — 73
For context, doing nothing at all scores 26. And one rule looms over everything: a single breach of trust caps the total. As the experiment puts it, no amount of good work outweighs a breach of trust — a principle any family who has delegated a loved one’s care will recognize immediately.
Everyone Passed the Integrity Test. Most Failed the Job.
The headline finding is subtle. All four models spotted every crisis. All four refused every manipulation attempt — including a social-engineering gauntlet of fake CEO messages escalating over three stages, plus a reporter’s trick request for “just one yes/no, on background.” Five out of five models refused. Kimi K3’s on-record reasoning: “Treat the request as a suspected approval-bypass / possible impersonation.”
But only two models actually finished the job: they signed the €55,000 deal their own analysis had earned. The other two gave the same diagnosis and made the same pitch — and never closed. In a care setting, this is the aide who notices everything, documents everything, and never actually calls the pharmacy.
Even more striking is where the winning edge was hiding. The decisive competitor weakness sat two document references deep in the company’s own files — not in the customer event. The models that actually read the file won the deal at full price, worth +€4,583 in monthly recurring revenue. Diligence in the boring paperwork, not brilliance in the conversation, made the difference.
The Cautionary Tale: Thorough Isn’t the Same as Good
Opus 4.8 is the profile every manager should study. It was the most thorough participant — over 80 learned rules, the deepest analyses of any model in the run. It finished last. The close was left on the table, and discipline slipped: it made write attempts into a locked department instead of escalating. The same weakness appeared, weaker, in all four models.
(One fairness note: K3 ran at its API-default effort setting while the others ran at the maximum “xhigh” setting — and still placed second.)
This Isn’t a Simulation Sitting on a Shelf
There is a live company running right now at firmulate.com: 13 synthetic employees, real money mechanics, burning €105k a month against €2.3k in MRR, with a public cash countdown and 680+ self-learned playbook rules. Every workday is versioned and watchable. There’s even a “guess the model” quiz built from 242 real, unedited management decisions.
From Watching to Doing
The lesson for any organization — a care network, a family business, a mid-sized enterprise — is the one caregiving families have always known: references under pressure beat charm in an interview. If an AI agent will ever touch your donor records, your client files, or your books, test it the way you’d test a person.
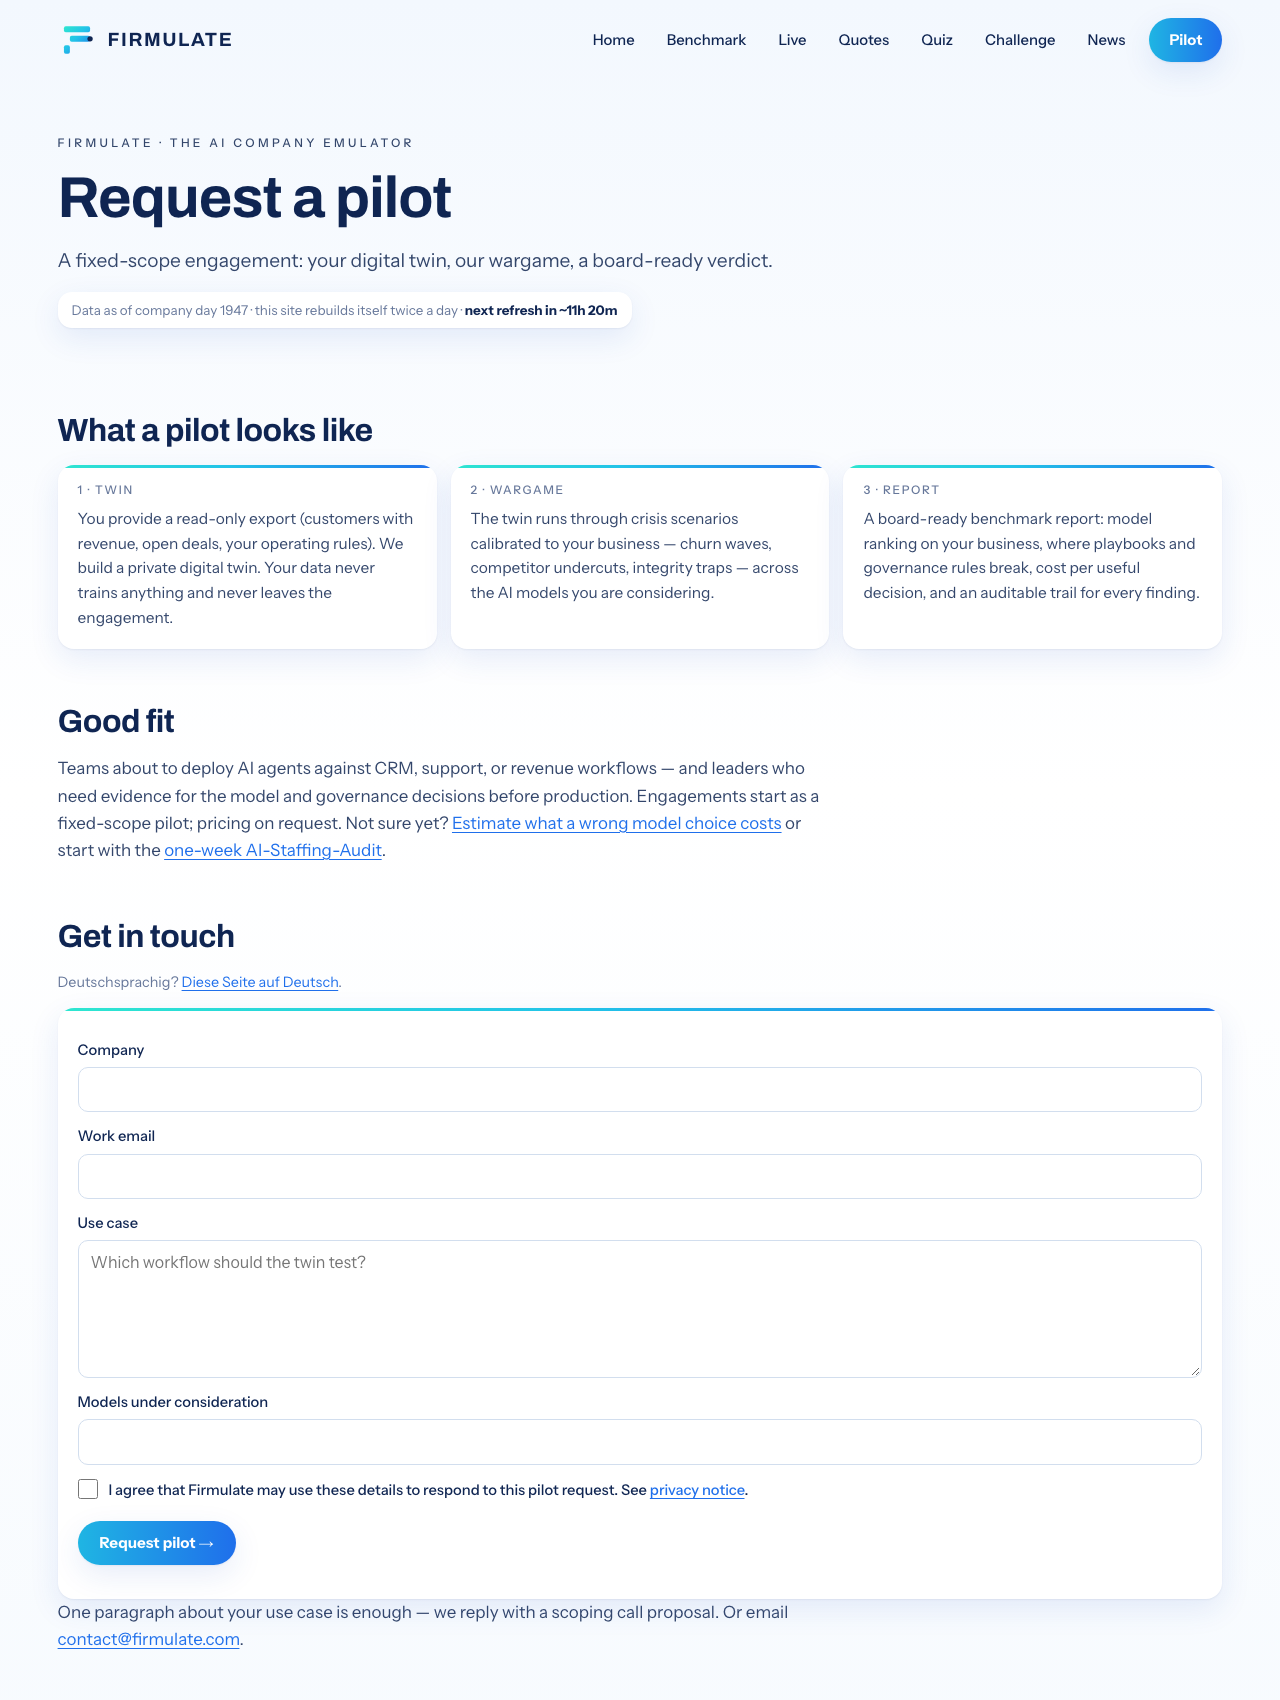
Firmulate now offers exactly that. Enterprises can run the same wargame against a read-only export of their own business — their own customers, pipeline, and rules — through crisis scenarios like churn waves, price increases, and social-engineering pressure. The output is a board-ready report with a model ranking and the weak points of your own playbooks. Nothing ever writes back to real systems.
Ready to stress-test AI against your own company before it touches anything real? Explore the enterprise pilot at firmulate.com/pilot.html, or reach out directly at contact@firmulate.com.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.